Inspect a typed request, not a promised answer
The example asks one choice question and one yes/no probability question about the same message. These are different dimensions: which queue owns the issue and whether important information is missing. The JSON below is request input, not a live result or a guarantee that a particular answer will be returned.
A valid response still needs a domain check. Confirm that every question ID is present, the type matches, and a chosen label belongs to your criteria. Missing confidence belongs in review, not in a made-up default score. Our API validates the provider response before treating it as a completed decision.
{
  "text": "My CSV export is missing the date column.",
  "questions": [
    {
      "id": "queue",
      "type": "choice",
      "instructions": "Choose the team responsible for the described issue.",
      "criteria": {
        "support": "Usage or account question.",
        "engineering": "Broken or missing behavior."
      }
    },
    {
      "id": "needs_details",
      "type": "noul",
      "instructions": "Is essential reproduction information missing?",
      "criteria": {
        "true": "Steps or the affected export are unclear.",
        "false": "Enough context to reproduce the issue is present."
      }
    }
  ],
  "threshold": 0.9
}
Keep the generation step separate
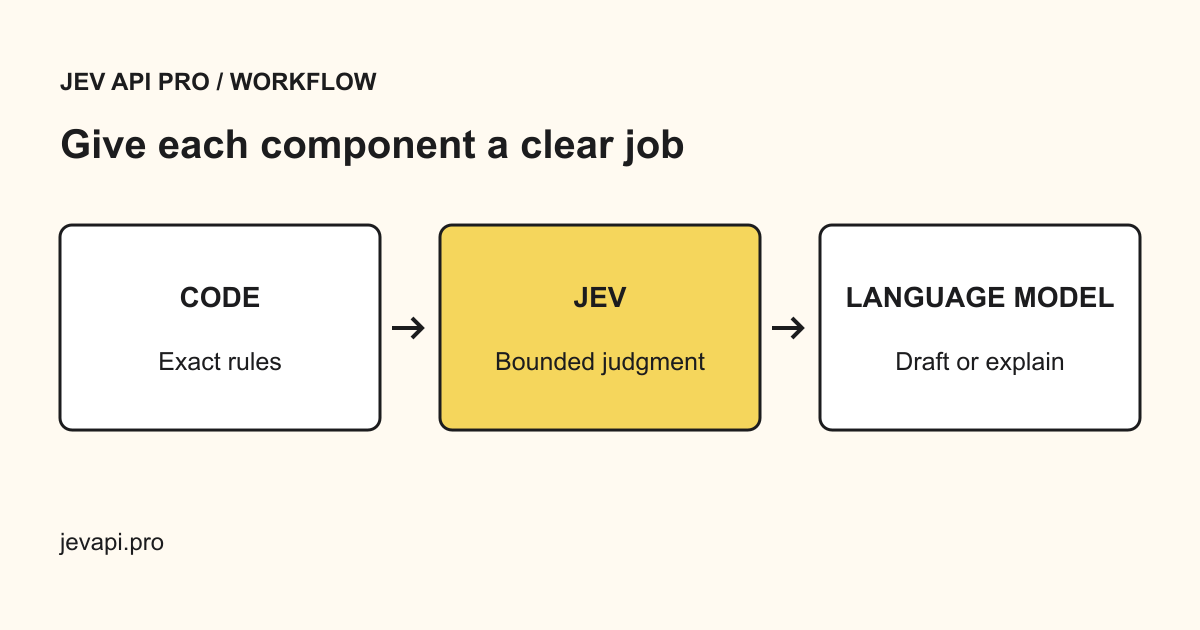
If the workflow also needs a customer reply, pass approved context to a generative model after the routing decision. Do not ask Jev to write a justification it does not return. Keep the generated draft visibly separate from the classifier output and review it before sending.
Compare the complete flow against simpler code and an existing generative-model baseline. Include retries, failed requests, review time and integration work in cost. A format that is easy to parse can improve engineering reliability without proving a higher task accuracy.
When a choice is enough
For routing, tagging, and prioritization, the next step may only need one of a few labels. A decision interface makes the candidate outcomes explicit and can expose probabilities without asking for a written explanation.
When generated text is the product
Drafting a customer reply, summarizing a long report, or extracting open-ended fields may call for a language model with structured outputs. This workspace does not claim that Jev replaces every text-generation task.
Compare accepted results, not only formats
Use the same labeled examples and compare accuracy, latency, failure rates, review volume, and total cost per accepted result. Valid JSON is a format guarantee, not a correctness guarantee. Do not reuse a provider’s public benchmark as proof of performance on your data.